- No one-size-fits-all Vector RAG works for simple document retrieval but fails at tracing drug-target-disease relationships, multi-hop reasoning, and explainable paths needed for regulatory compliance.
- $7.5B market by 2031 The pharma knowledge management software market is projected to grow from $1.23 billion in 2023 to $7.5 billion by 2031.
- Vector RAG sweet spot Vector RAG excels at literature reviews, FDA/EMA document retrieval, clinical report summarization, and SOP queries, with rapid, cost-effective deployment.
- Vector RAG failure modes Key weaknesses include relationship blindness, context collapse from top-N passage limits, reasoning gaps, and an explainability deficit for compliance.
- Graphs enable reasoning Knowledge graphs traverse paths like Gene X to Protein Y to Pathway Z to Disease A; AstraZeneca's Biological Insights Graph surfaces hidden gene-disease connections.
- Hybrid architectures win Leading organizations combine vector databases for semantic document search with knowledge graphs for relationship reasoning, deploying each technology where it performs best.
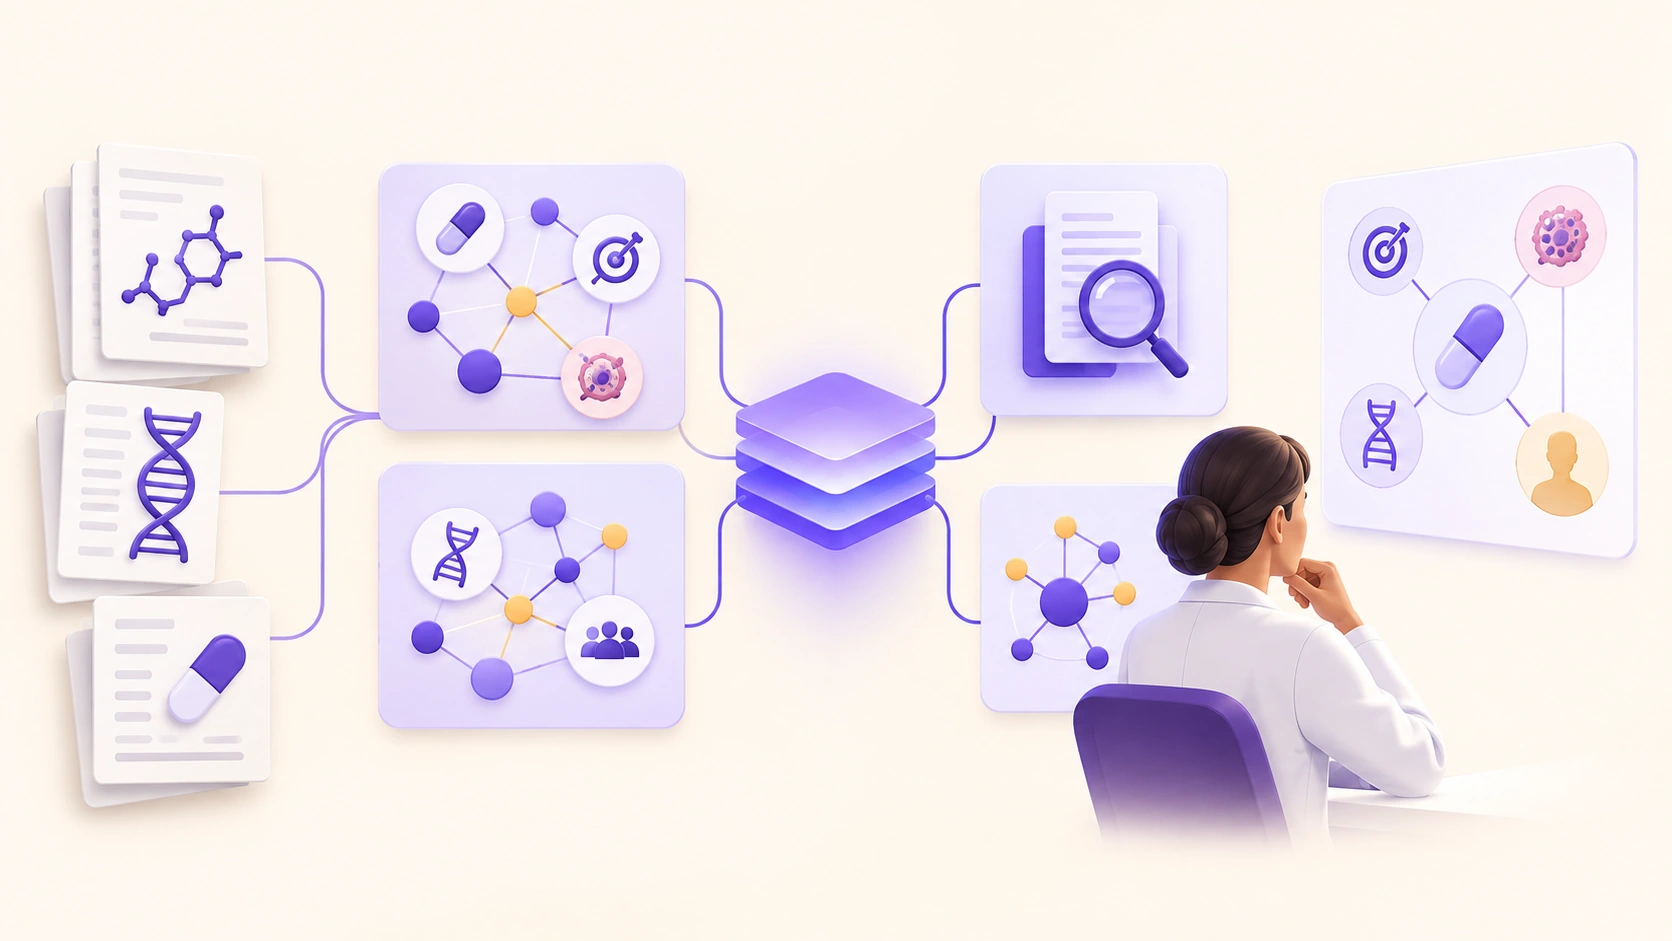
Pharma knowledge management has a shape problem.
A vector RAG system is good at one specific thing: finding the paragraph that sounds most like your question. That works fine right up until the answer isn't sitting in one paragraph. It's spread across a chain. This drug hits that target. The target sits in a pathway implicated in a disease. That disease already has three approved therapies working through a related mechanism. Get pharmaceutical knowledge management wrong and the cost isn't a mediocre search result. It's a missed repurposing signal. It's a regulatory submission that can't show its own reasoning. It's a safety pattern that two systems each half-saw and neither connected.
The market is moving fast enough to notice. Verified Market Research sizes the pharma knowledge management software market at $1.23 billion in 2023, growing to $7.5 billion by 2031 — a 15.24% compound annual growth rate. Other firms size the same category using different numbers: Market Research Future puts 2023 nearer $1.88 billion, reaching $6.11 billion by 2030; another report lands at $1.5 billion growing to just $2.63 billion by 2031. That spread is wide. It's normal for a market definition this new and this loosely bounded — "pharma knowledge management software" isn't a single, standardized product category yet. What doesn't vary across the estimates is the direction: the pharmaceutical industry is buying more of this software. Increasingly, the systems it buys have to make an actual architecture decision, not just a vendor decision.
This piece is that architecture decision, worked through honestly. Not "RAG vs. graphs" as a general enterprise-AI concept — a companion piece on this website already covers that ground in depth. This is the pharma-specific version. It covers what breaks when generic retrieval meets drug-target-disease reasoning, and what two real, named, currently-operating pharma knowledge graphs do. It also covers what Microsoft's own GraphRAG research does and doesn't claim. It also covers where a hybrid approach — not a single winner — earns its complexity.
Why Generic RAG Falls Short for Pharma Knowledge Management
Most enterprise knowledge management is document retrieval with better search. Find the policy, find the ticket, find the paragraph. Knowledge management in the pharmaceutical industry carries that same document-retrieval layer — SOPs, literature, regulatory guidance all still need to be found. But it also carries a second, harder layer underneath: relationships that matter more than any single document ever states on its own. Both layers stop at explicit knowledge — whatever already got written down. Neither a vector index nor a graph reaches tacit knowledge: what a scientist knows but never writes down.
A target-disease connection isn't usually written down as one clean sentence. It's assembled from a genetic-association study, a pathway-biology paper, an animal-model result, and a clinical observation. That's four different documents, four different vocabularies — no single paragraph that says "these connect." A vector index can retrieve all four documents if you ask the right question. It has no native mechanism for stating that they describe the same underlying chain. That's a structural gap, not a tuning problem. No amount of better embeddings or reranking teaches cosine similarity to represent "A causes B causes C" as something distinct from "A merely resembles C in wording."
Regulatory explainability raises the stakes further. When a submission reviewer or an internal QA function asks how a conclusion was reached, "these paragraphs scored highest on semantic similarity" isn't an answer. It's a description of the search mechanism, not the reasoning. A relationship-based system that can show node, edge, node, edge, evidence source is answering a fundamentally different question. It's the question regulatory work asks. That combination is multi-step biological reasoning plus an audit trail regulators can follow. It's what makes pharma knowledge management software a harder design problem than the equivalent tool built for, say, sales-team document search.
Vector RAG in Pharma: Where It Earns Its Keep, and Where It Breaks
Vector RAG isn't the wrong tool for pharma. It's the right tool for a specific, large slice of the work, and dismissing it wholesale would be its own kind of overclaim.
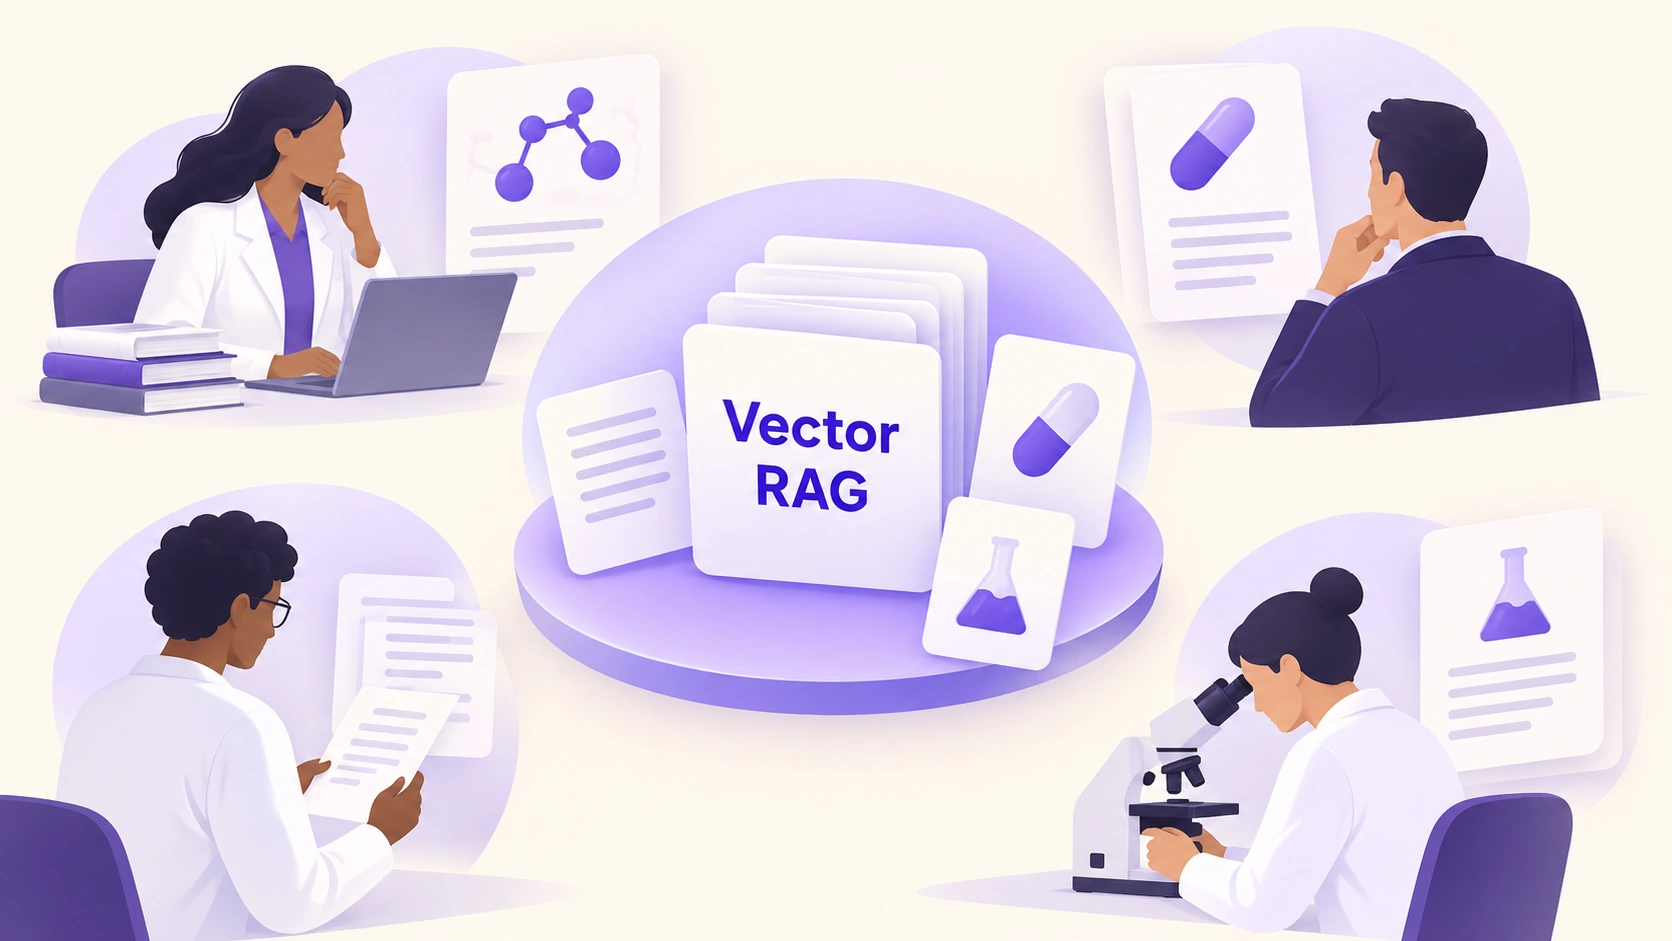
Where it holds up. Literature monitoring across a fast-moving therapeutic area is a semantic-search problem RAG solves well. Think new PubMed entries, conference abstracts, clinical trial results, competitor publications. Regulatory document retrieval is the same shape of problem. It means pulling the right FDA guidance or EMA reflection paper from a regulatory repository by meaning, not exact keyword match. So is clinical study report summarization. It means condensing a 200-page CSR into the sections a medical writer needs. So are SOP queries, like "what's our procedure for handling an out-of-specification result." That's the kind of single-document lookup vector search was built for. Across all of these, RAG's real advantages hold. It deploys fast against the document management systems many pharmaceutical companies already have. It updates in near-real-time as new literature lands, and it costs a fraction of what a maintained knowledge graph costs to stand up.
Where it breaks. The failure mode has a specific shape: multi-hop reasoning. Take a question like "which already-approved drugs hit a target implicated in this disease's pathway." Answering it requires walking Drug A → Target B → Pathway C → Disease D as a connected chain. Vector search can retrieve documents that separately mention A, B, C, and D. It cannot represent that they form one path. Nothing in a chunk-and-embed pipeline encodes "connects to" as a distinct, traversable relationship. Three specific consequences follow from that gap. Relationship blindness: two entities can be strongly, biologically connected — a target and the pathway it sits in — without ever appearing in the same sentence anywhere in the knowledge base. A similarity search never surfaces that connection at all. Context collapse: chunking a document into retrievable pieces routinely separates a claim from the qualifier or citation that gives it meaning. The retrieved chunk can be technically accurate and still misleading on its own. Explainability deficit: a 0.87 cosine-similarity score isn't a reasoning path. It cannot be handed to a regulatory reviewer as evidence of how a conclusion was reached. It isn't evidence of a conclusion — it's evidence of word-choice overlap.
None of that makes vector RAG a bad tool. It makes it the wrong tool for one specific, high-value category of pharmaceutical question. That's the category graph-based systems exist to answer.
Knowledge Graphs in Pharma: What AstraZeneca and the Open Targets Consortium Actually Built
A knowledge graph earns its added complexity by doing the one thing vector search structurally can't: traversing an explicit chain of relationships — Gene X → Protein Y → Pathway Z → Disease A. It shows the exact path it followed to get there. Two real, currently-operating systems make that concrete rather than theoretical.
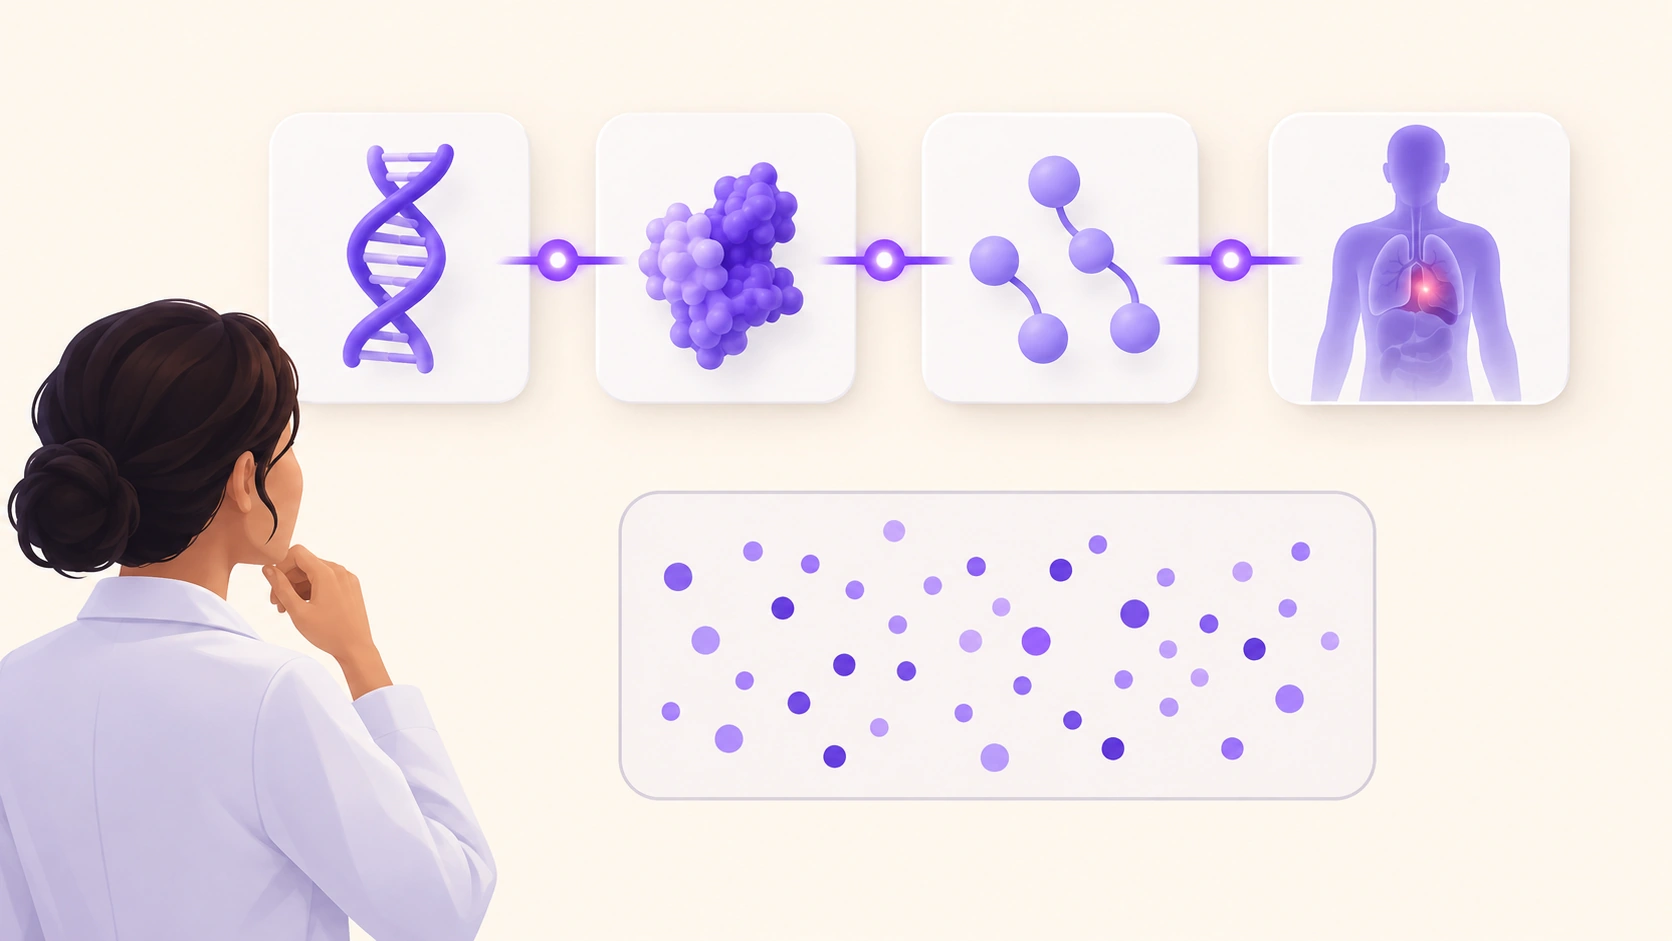
AstraZeneca's Biological Insights Knowledge Graph (BIKG). The correct name is Biological Insights *Knowledge* Graph. That detail is worth getting right, since it's easy to drop the middle word and describe something vaguer than what exists. BIKG is real and peer-reviewed. It's described in a 2021 bioRxiv preprint on using an integrated knowledge graph to support drug development, and covered in a 2024 Science Advances paper on phenome-wide target discovery. It does what the underlying claim describes. It integrates AstraZeneca's own internal, proprietary experimental and drug-development data with public databases — including ChEMBL and Ensembl. It also draws in relationships extracted from scientific literature via NLP. In total, it draws on 55 public, licensed, and internal data sources. The scale is specific and checkable: roughly 14 million nodes and 136 million edges, of which about 8.7 million are gene-gene interactions. AstraZeneca's own researchers built a graph neural network framework, Mantis-ML 2.0, on top of BIKG — incorporating UK Biobank data — to score gene-disease probability across the phenome. Scored against 5,220 diseases, it reported a median ROC-AUC of 0.90 and roughly a 6.9% average lift in classification power. The explicit goal, in the researchers' own framing, is inferring gene-disease connections that are "hidden in plain sight." These are real relationships that exist in the combined data but that no single source, and no simple document search, would surface on its own. That is a materially accurate description of what the underlying claim gets at. It replaces the vague version — "helps scientists discover hidden connections" — with what was actually published.
The Open Targets Platform. This is the sharper, more current illustration of drug-target-disease reasoning. It's a stronger example than a single-company internal tool because it's a shared, public, multi-sponsor resource. Open Targets is a consortium led by EMBL's European Bioinformatics Institute (EMBL-EBI). GSK, Genentech, MSD, Pfizer, Sanofi, and the Wellcome Sanger Institute jointly fund and use it. That's six major life-sciences organizations pooling data into one centralized knowledge graph, rather than each rebuilding the same infrastructure separately. It's been published and peer-reviewed in Nucleic Acids Research across multiple editions, most recently in 2025. That matters: this isn't a historical project that stalled after its funding ended — it's actively maintained. The Platform aggregates evidence from genetics, genomics, transcriptomics, known drug status, animal models, and text-mined literature. That literature base is more than 26 million PubMed abstracts and 1.2 million open-access full texts, across roughly 26 underlying data sources. It scores several million target-disease associations, with each association's evidence type attached and visible. That evidence attachment is the explainability piece in practice. A researcher doesn't just get "Target X is linked to Disease Y" — they get which evidence types support that link, and how strong each one is. That's the "Drug A → Target B → Pathway C → Disease D" pattern the underlying claim describes — except it isn't hypothetical. It's a live platform six major pharmaceutical companies co-fund, because a single vector index over their combined literature couldn't do this job.
What Microsoft's GraphRAG Research Actually Shows
Microsoft Research's GraphRAG project is real. It's the most-cited attempt to formalize graph-based retrieval as a general technique. It's worth being precise about what its own primary research says. This is the kind of claim that gets rounded up as it travels through secondary sources.
GraphRAG was published by Jonathan Larson and Steven Truitt on the Microsoft Research blog in February 2024. The system has an LLM extract entities and relationships from a document set into an actual graph. It then clusters that graph into hierarchical communities, and pre-summarizes each community before retrieval happens. The real, confirmed claim: GraphRAG "consistently outperforms" baseline RAG on comprehensiveness, diversity, and what the researchers call "human enfranchisement." That means how well an answer equips someone to act on it. That's a genuine, meaningful edge. It's also a *qualitative* claim, worth being exact about. Those three metrics were evaluated by an LLM grader, not measured as a hard accuracy percentage. Microsoft's own primary post does not publish a specific accuracy number anywhere. On faithfulness specifically, GraphRAG comes out at roughly *parity* with baseline RAG — not an improvement. Faithfulness here is measured with SelfCheckGPT, a check for whether an answer stays grounded in the source material. That's an important nuance the framing "enhanced accuracy" tends to flatten. GraphRAG's real edge isn't that it hallucinates less than vector RAG on a given fact. It's that it answers a harder, multi-part class of question better, and shows its work while doing it.
That second half — showing its work — is the strongest, best-documented part of the claim. It holds up well under scrutiny. Microsoft's own post walks through how GraphRAG traces every assertion back to its original source document. The stated purpose is so "a human user can quickly and accurately audit the LLM's output directly against the original source material." That auditability is real, it's demonstrated with a worked example in Microsoft's own published research, and it's the piece that matters most for a regulatory context.
One more thing worth naming: Microsoft's own research post never uses the term "multi-hop." The underlying capability it targets is real and correctly described. The post explicitly frames baseline RAG's core weakness as failing to "connect the dots" when an answer requires "traversing disparate pieces of information through their shared attributes." That phrase is what multi-hop reasoning means in practice, even though the specific label itself is industry shorthand rather than Microsoft's own vocabulary. Readers researching this topic will also run into secondary sources — vendor blogs, SEO-optimized explainers. Some attach a specific number to GraphRAG's multi-hop performance, in some cases claiming accuracy gains above 90% against baseline RAG. None of that traces back to Microsoft's own published research, which contains no such figure. Treat any precise percentage you see attached to GraphRAG secondhand with the same skepticism this website applies to every other unsourced statistic. Ask which benchmark. Ask against what baseline. And don't repeat it until you can answer both.
Hybrid Architecture: Matching the Tool to the Pharma Knowledge Management Task
The honest answer for most pharmaceutical organizations isn't "pick one." It's matching each task to the architecture built for its actual shape. Increasingly, that means running both inside the same pharma knowledge management (KM) software stack. Vector search handles semantic document retrieval. A knowledge graph handles relationship reasoning. A semantic layer often bridges the two, keeping vocabulary consistent across both. SciBite, now part of Elsevier, is a real, named example of a vendor built around that bridge. Its ontology-management tooling turns unstructured pharmaceutical text into harmonized, machine-readable data that a graph can consume. That's a different model than treating semantic search and graph reasoning as competing purchases.
Applied to specific pharmaceutical workflows, the split looks like this. Vector RAG fits regulatory intelligence and document retrieval, literature monitoring, clinical study report summarization, and SOP queries. These are cases where the answer lives inside one document, and speed of deployment matters more than relationship depth. Graph-based systems fit drug-target identification (the Open Targets pattern), adverse-event causality analysis, multi-target therapy discovery, and regulatory pathway analysis. These are cases where the answer is a chain, not a paragraph. Hybrid architectures fit competitive intelligence, integrated safety analysis, and research and development portfolio optimization. This work needs both a wide semantic sweep across unstructured text and a precise relationship trace, once the relevant entities are found.
Regulatory data itself is drifting toward a structure that makes this decision less theoretical. ISO IDMP (Identification of Medicinal Products) is pushing regulatory submissions toward standardized, structured product data, across the pharmaceutical product lifecycle, rather than free-text documents. eCTD submission formats are built around that same direction. Structured, relationship-rich regulatory data is the shape a graph represents natively. A flat document index doesn't. That's not a hypothetical future state. It's the direction the regulatory data standards are already moving — standards the pharmaceutical industry already has to comply with.
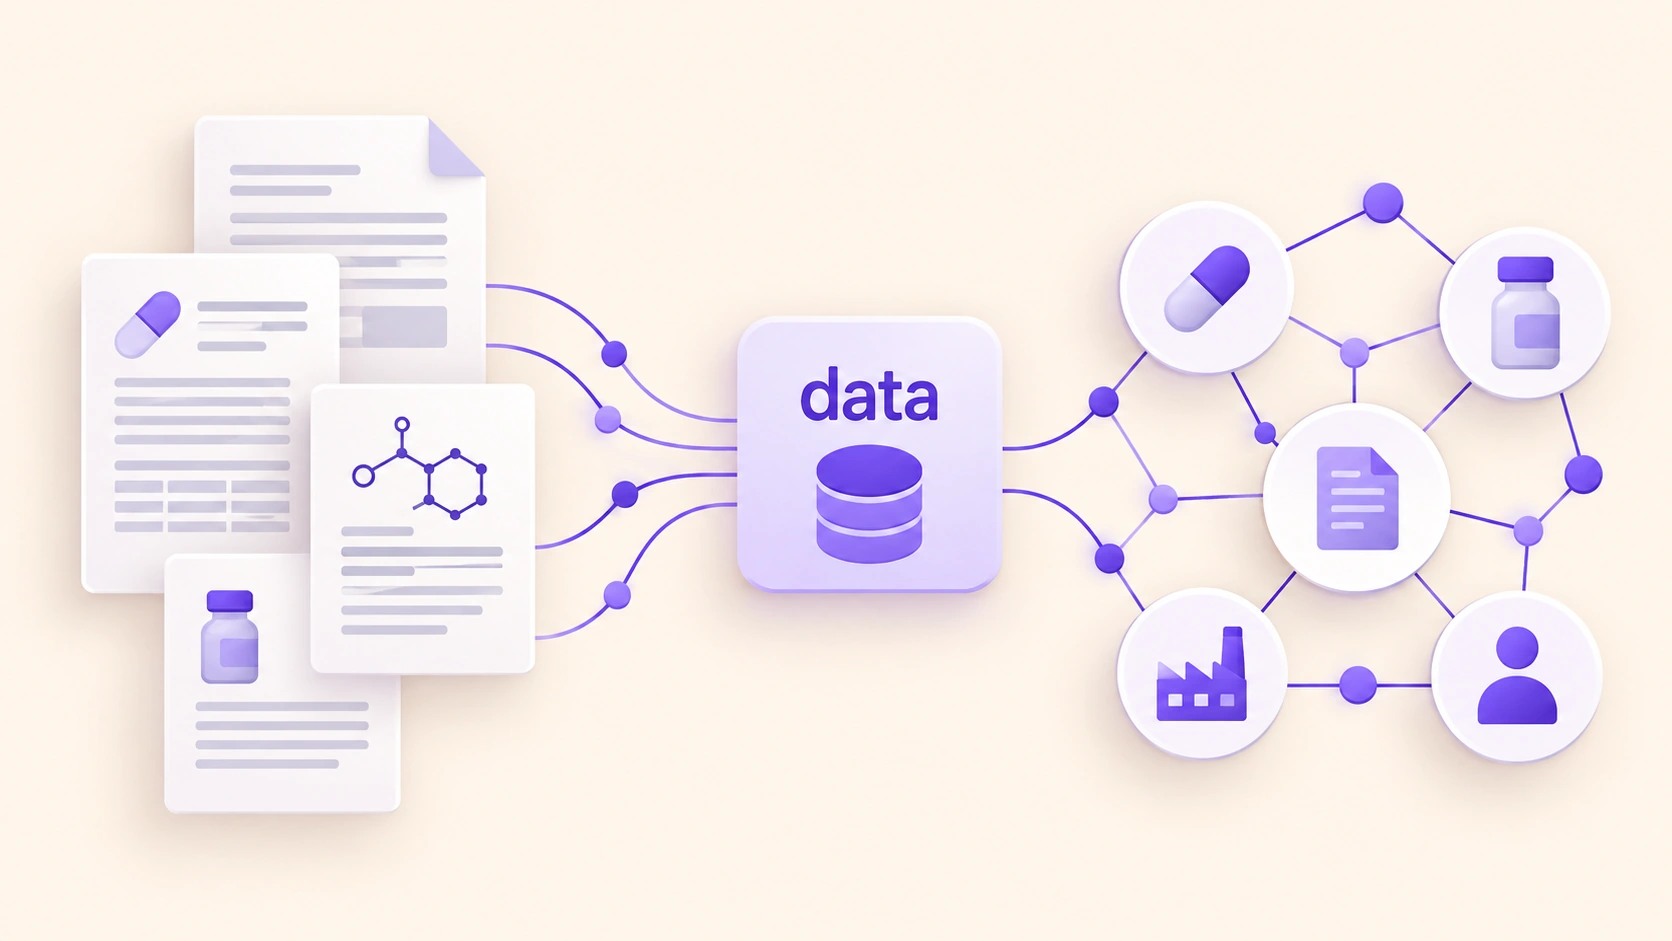
Implementation costs follow the same split. Vector RAG is cheaper and faster to stand up because it works against documents a pharma company already has. No ontology-design phase is required. A knowledge graph costs more upfront. Entity resolution, ontology design, and data management are real, ongoing engineering work, not a one-time setup. So is integrating internal experimental data with public sources like ChEMBL or DrugBank. That cost doesn't disappear once the graph is built. New experimental data keeps arriving and has to be reconciled continuously. That's the same way AstraZeneca's own team maintains BIKG, rather than treating it as a finished asset.
Where NextLevel.AI Actually Fits
Here's the direct version: NextLevel.AI is a voice AI company. We don't build pharmaceutical knowledge-graph infrastructure. We don't run architecture-selection consulting engagements deciding between vector RAG and graph-based systems for a pharma R&D or regulatory-affairs team. And we don't have a roster of "specialized pharmaceutical AI agents" for that job. We checked that claim against our own approved claims about what NextLevel has built. That's the same discipline this whole piece has been applying to AstraZeneca's and Microsoft's research. It isn't there. That claim has also appeared, worded almost identically, on a live page on this website — this article replaces it rather than repeating it.
Where we do intersect with this topic is narrower, and worth stating plainly rather than stretching. Pharmaceutical and healthcare organizations that deploy a NextLevel voice agent depend on the same underlying principle this entire article has been about. Take a Medical AI Chatbot fielding patient questions, for instance. An AI system is only as trustworthy as what grounds its answers. That's a much smaller-scale version of the pharma knowledge management problem — conversational rather than architectural. It doesn't require a knowledge graph to get right. It does require the same honesty about what's verified versus what sounds plausible. Where compliance matters — and in pharma and healthcare it always does — that work runs on infrastructure independently attested with a SOC 2 Type I report and ISO/IEC 27001:2022 certification. That's aligned with HIPAA, GDPR, and PDPL, across roughly 30 languages. If that narrower, conversational piece is what you're evaluating, book a call. We'll tell you plainly whether it fits, including the parts of pharma knowledge management we're not the right vendor for.
Frequently Asked Questions
What's the real difference between vector RAG and graph-based AI for pharma knowledge management?
Vector RAG retrieves documents based on semantic similarity. It finds the paragraph that reads most like your question. Graph-based AI traverses explicit relationships between entities instead — genes, targets, pathways, diseases. It follows a connected chain even when no single document states the full path. For a single-document lookup, RAG is faster and cheaper. For a multi-step biological question, only a graph structurally represents the connection at all.
Which approach is better for regulatory intelligence and compliance?
It depends on the task. Vector RAG handles regulatory document retrieval well. It finds the right FDA or EMA guidance by meaning. But when a submission or an internal audit needs to show *how* a conclusion was reached, graph-based systems have the real advantage. That advantage is an explicit, traceable path (node, edge, node, evidence source) that a reviewer can follow. A similarity score alone doesn't satisfy that requirement.
How do implementation costs compare between vector RAG and knowledge graph systems?
Vector RAG is meaningfully cheaper and faster to deploy. It runs against a document repository a pharmaceutical company already has, with no ontology-design phase. Knowledge graphs cost more upfront. Entity resolution and ontology design are real engineering work. So is integrating internal experimental data with public sources like DrugBank or ChEMBL. That cost is ongoing, not one-time. AstraZeneca's own BIKG team maintains it continuously as new data arrives, rather than treating it as finished.
What pharmaceutical use cases benefit most from graph-based systems specifically?
Drug-target identification is the clearest case. It's what the Open Targets Platform — backed by EMBL-EBI, GSK, Pfizer, Sanofi, and other sponsors — is built to do at scale. Adverse-event causality analysis, multi-target therapy discovery, and regulatory pathway analysis follow the same pattern. Each requires connecting several separate facts into one chain. That's a structural strength of graphs, and a structural weakness of similarity search.
Can vector RAG and knowledge graphs be combined in one pharma knowledge management system?
Yes. For most organizations, that's the realistic end state for pharma KM, rather than picking a single winner. Vector search handles the semantic document layer — literature, SOPs, regulatory guidance. A knowledge graph handles relationship reasoning on top of it. Vendors like SciBite (now part of Elsevier) build toward that bridge. They turn unstructured pharmaceutical text into the structured, harmonized data a graph can consume.
How does each approach handle explainability for regulators?
Differently, and the gap matters in a regulated industry. A vector RAG system can tell you which documents it retrieved. But a cosine-similarity score isn't a reasoning path — it can't show how a conclusion was assembled. Graph-based systems, including Microsoft Research's own published GraphRAG work, are built around tracing every assertion back to its source. That produces an audit trail a human reviewer can check. That's the specific, verified strength of the graph approach. It's not a vague "more accurate" claim — it's a demonstrated, traceable path.
What expertise does a pharmaceutical organization need to build and maintain a knowledge graph?
More than a one-time integration project requires. Entity resolution is real, ongoing work that doesn't stop once the graph launches. It means deciding that a compound ID in an internal system and a ChEMBL identifier refer to the same molecule. Ontology design needs domain expertise, not just engineering. The graph also has to be kept current as new experimental and literature data arrives. That's the same continuous-maintenance model AstraZeneca applies to BIKG, and the one the Open Targets consortium applies to its own platform. Budget for a maintained system, not a finished deliverable.
About the Author
Michael Lazor is Founder and CEO of NextLevel.AI. He writes and reviews content about the economics, engineering, evaluation, and production deployment of voice AI.