- Cost and approval odds The median capitalized R&D investment to bring a new drug to market was estimated at $985.3 million, with only about 12% of drugs entering clinical trials ultimately approved by the FDA.
- Three core problems Traditional regulatory intelligence tools create information overload without insight, reactive rather than proactive strategy, and disconnected data that produces strategic blind spots.
- Weeks to minutes Clinical Pharmacologist Digital Workers automate FDA Orange Book analysis, patent research, and regulatory pathway evaluation, completing in minutes work that traditionally required weeks of manual cross-referencing.
- Hybrid architecture The platform combines a Neo4j knowledge graph, an OpenSearch document layer, a Mixture-of-Experts agent set, and a natural chat/voice interface, connecting DrugBank, ChEMBL, FDA records, and patent databases.
- Research Agent scope The Research Agent evaluates 505(b)(1) and 505(b)(2) pathways, analyzes RLD specifications and therapeutic equivalence, identifies patents, exclusivity periods, and Paragraph IV opportunities, and maps competitive landscapes.
- Proactive monitoring Real-time monitoring across FDA, EMA, and other agencies delivers proactive alerts on patent expirations and competitive entries, with continuous learning that improves accuracy over time.
Search "automating regulatory intelligence" and you land on two different stories — that's true of a handful of other pharma AI topics too.
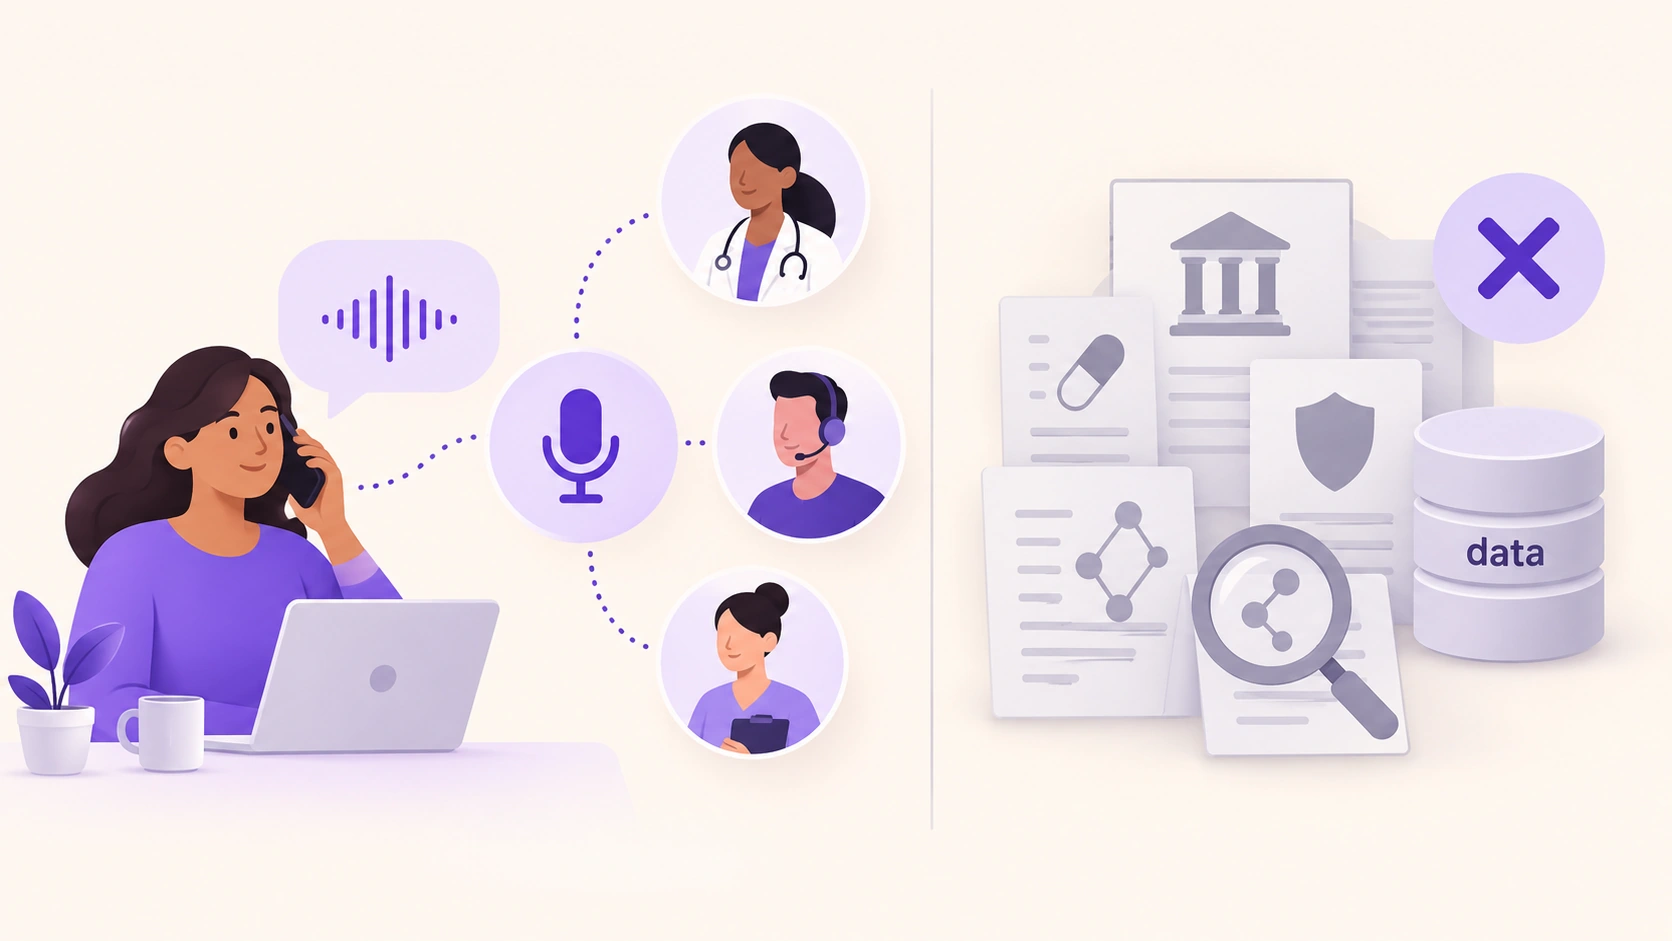
One describes a roster of named AI specialists: a Clinical Pharmacologist Digital Worker, a Regulatory Affairs agent, a Competitive Intelligence agent. They supposedly run on a Neo4j knowledge graph and a "Mixture of Experts" architecture, cross-referencing the FDA Orange Book, patent filings, and regulatory pathways in minutes instead of weeks. The other story comes from people who work in pharma regulatory intelligence: the regulatory affairs software vendors, the health authorities, and the researchers. That includes Certara's submission and pharmacometrics software, used across the industry. It includes Veeva's regulatory information management platform, running inside most of the top 20 pharma companies. And it includes the FDA and EMA's own newly published guidance on how they expect AI to be used — and not used — in drug development.
This article is the second kind. NextLevel.AI builds custom voice AI agents for business, including healthcare-adjacent ones. We do not build regulatory intelligence software, patent-monitoring platforms, or a knowledge-graph system for tracking FDA and EMA activity. An earlier version of this exact page described AI Digital Workers that could do precisely that. They supposedly analyzed Orange Book data, cross-referenced patents, and evaluated regulatory pathways, all on a "Mixture of Experts" system layered over a Neo4j knowledge graph. Those claims describe a product this company has never built and doesn't operate. This version corrects that. What follows is what real, checkable sources say about artificial intelligence in regulatory affairs today. Specifically, it covers where NextLevel does and doesn't belong in that picture.
The Real Cost Problem Regulatory Intelligence Is Supposed to Solve
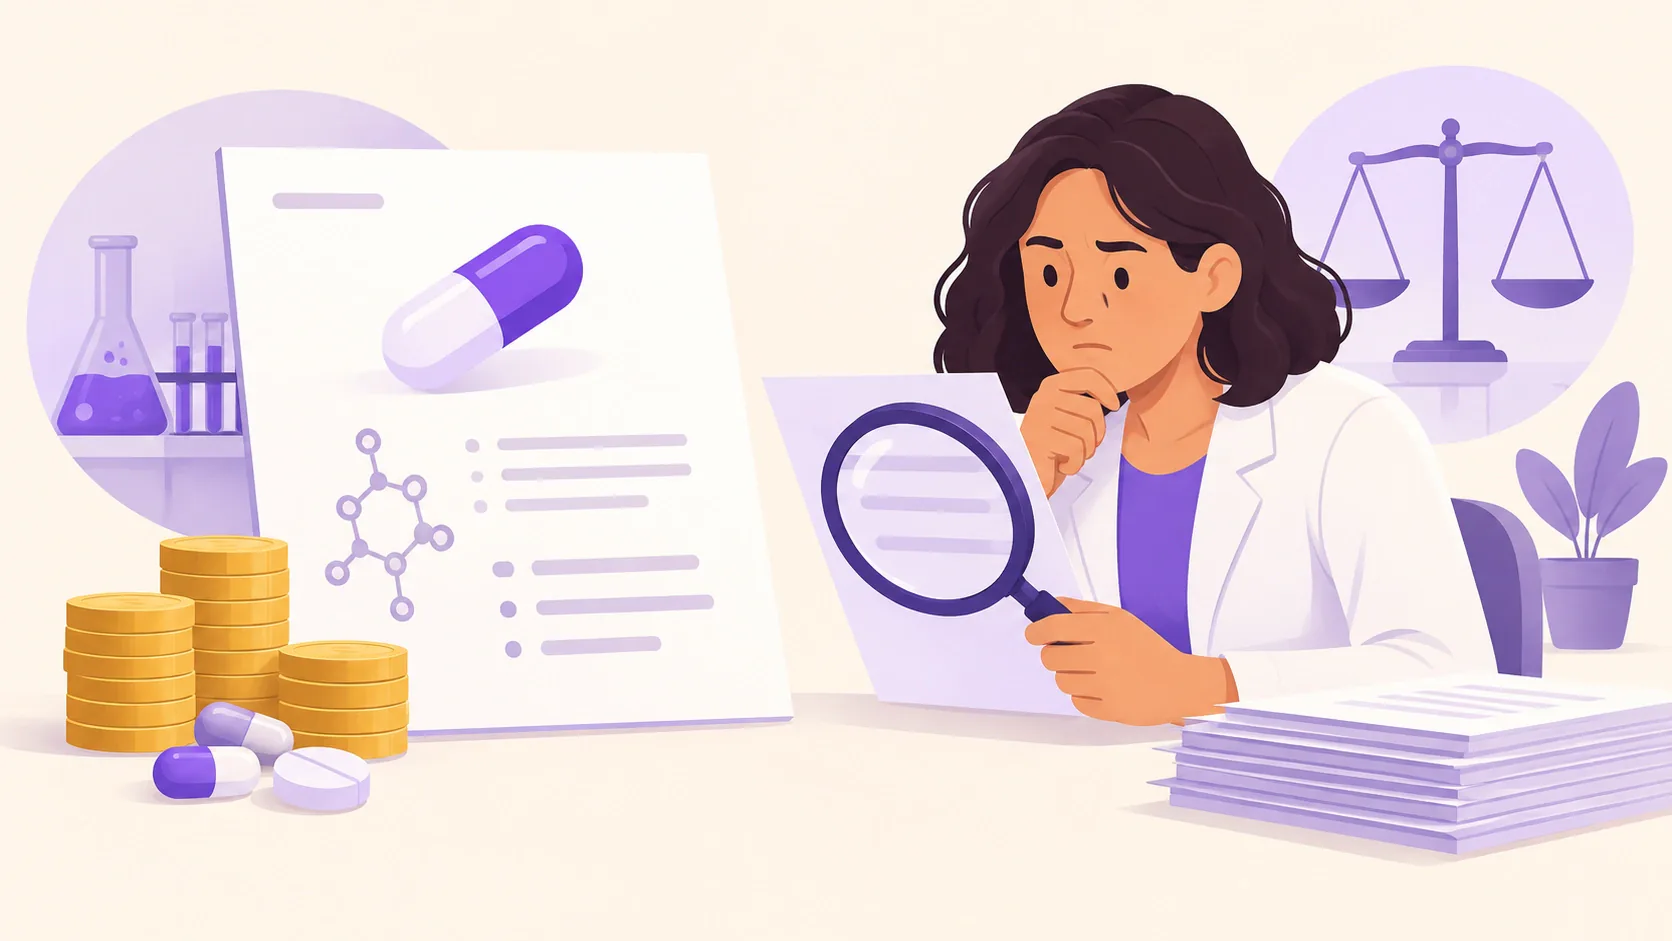
The pitch's anxiety is real, even where its fix isn't. Bringing a new drug to market is extraordinarily expensive across the full span of product development, and most candidates that enter clinical trials never get there. That's the actual reason a pharmaceutical company invests in regulatory intelligence: the discipline of tracking regulatory pathways, patent landscapes, and health authority activity. Done well, it means staying ahead of regulatory changes and making good strategic decisions about market entry before a competitor does, or before a filing deadline is missed. Get the underlying numbers wrong, though, and you undercut the very case you're trying to make.
Even the One Citation That Sounds Airtight Needs a Second Look
The original draft of this page opened with a specific, checkable-sounding claim: "research published in JAMA Network Open" put the median capitalized R&D investment to bring a new drug to market at $985.3 million. Only about 12 percent of drugs entering clinical trials, it said, ultimately won FDA approval. It's a real-sounding citation. That's exactly why it's worth checking directly rather than repeating.
Here's what's actually there. The $985.3 million figure traces to a real study: Wouters, McKee, and Luyten, published in *JAMA* — the flagship journal — on March 3, 2020. That's not *JAMA Network Open*, which is a related but separate open-access journal in the same network. The distinction matters to anyone trying to verify the citation themselves. More importantly, $985.3 million was the study's original, since-corrected number. In September 2022, JAMA published a correction. One of the study's source datasets had misreported a Phase 2 trial success rate. Once the authors reran their analysis with the corrected figure, the median capitalized R&D investment rose to $1,141.7 million (95% CI, $888.1 million–$1,480.8 million). The $985.3 million figure still circulating in vendor pitches is the pre-correction number.
The "about 12 percent" approval-rate figure has a different problem: it isn't from that study at all. The JAMA paper cites it only as background context. That context comes from a separate analysis — Wong, Siah, and Lo, published in *Biostatistics* in 2019. That study examined more than 406,000 clinical-trial-phase entries and found that 13.8% of drugs entering Phase 1 eventually won FDA approval. A different, more recent study looked at this too — this one actually published in *JAMA Network Open*, in 2024. It used a different cost-estimation methodology and arrived at an overall probability of success of 8.5%. Both of those figures are real and checkable. Neither is the study the original citation named. The honest range across multiple, independently published sources is roughly 8% to 14%, depending on dataset and time period — not a single flat "12%."
None of this changes the point the citation was reaching for. Developing a new drug is a billion-dollar bet with long odds, in any of these honestly sourced versions of the number. But a pitch that gets a checkable citation wrong in two different ways, in its opening sentence, is a pitch worth reading the rest of with extra scrutiny.
The Operational Problem Is Real, Even Though the Platform Isn't
Strip away the fabricated platform and there's still a genuine operational problem underneath it. Regulatory intelligence work means continuously tracking FDA Orange Book listings, patent and exclusivity statuses, competitor filings, new regulatory requirements, and evolving guidance from FDA, EMA, and other health authorities. Those sources are large, only partly structured, and updated on their own schedules — not the reviewing team's. Missing a patent expiration, a shifted pathway, or a competitor's filing is a genuinely expensive mistake at this stage of a drug's life.
Market researchers estimate the regulatory information management software market at roughly $2.4–2.7 billion in 2026, growing at around 11% a year. A narrower "AI in regulatory affairs" segment is estimated separately at about $1.9 billion in 2026. Treat those specific figures as directional — commercial market-sizing reports vary by firm and methodology. But the direction itself is real. This is a large, growing category serving pharmaceutical companies across global markets, with actual vendors and actual regulatory-agency activity in it. That's exactly why a pitch in this space doesn't need a fabricated platform to sound credible. The real, AI-driven version of this story is compelling enough on its own.
What Real Regulatory Intelligence Tools — and Regulators — Are Actually Doing
A handful of named companies make up the actual current state of AI in regulatory affairs. So do the regulators themselves. Their work is independently checkable, in a way a roster of job titles isn't.
Certara is one of the more established names in regulatory-facing pharma software. Its GlobalSubmit platform handles eCTD publishing and validation for regulatory submissions. Its CoAuthor tool uses generative AI to draft regulatory-document content and templates. The company's own description: "accelerate the creation of regulatory documents with AI-generated content, freeing up writers for key analysis, messaging, and refinement" — with a human still doing that analysis, messaging, and refinement. Certara's Phoenix modeling platform feeds the pharmacometrics work behind regulatory submissions. It's reported to be used by more than 75 of the top 100 pharmaceutical companies. Adoption reaches inside regulatory agencies too, including the FDA, EMA, PMDA, and NMPA. That's a real, named product with a real, named customer base — the kind of track record a "Mixture of Experts" architecture diagram doesn't come with by default.
Veeva Vault RIM is the regulatory information management suite built on Veeva's Vault platform. Hundreds of pharmaceutical companies use it, including most of the top 20, to plan, track, and report on global product registrations and regulatory submissions. In October 2025, Veeva announced Veeva AI Agents — agentic AI features layered across its Vault applications, including regulatory. The rollout is staged, not instant. Commercial agents shipped first in December 2025. Regulatory- and clinical-operations-specific agents, covering functions like regulatory submission tracking, are named for release around August 2026. That staged, dated rollout is itself informative. A company that builds this technology ships it in phases with named release windows. That's regulatory change management in practice — not a single fully formed platform that already does everything on day one.
Deep Pharma Intelligence, the analytics arm of Deep Knowledge Group, and Deep Intelligent Pharma, a separate Singapore-based company, both work in adjacent territory. The former does biotech and pharma market-intelligence reporting. The latter builds AI tools that help automate regulatory-submission drafting and translate regulatory content for global health authorities. Neither claims a Neo4j knowledge graph running "Clinical Pharmacologist" agents. They're named here for the same reason Certara and Veeva are: to give a reader something real and checkable to compare a vendor pitch against.
The regulators themselves are worth naming too. They're the ones setting the terms for artificial intelligence in regulatory affairs right now. The FDA's Orange Book — formally, *Approved Drug Products with Therapeutic Equivalence Evaluations* — is the real, public database a pitch like this leans on. It lists approved drugs, patents, exclusivity periods, and therapeutic equivalence codes. A generic applicant's Paragraph IV patent challenge against a listed patent is a matter of public record there — not a proprietary insight any AI vendor can claim to have surfaced first. On the AI-specific side, the FDA released draft guidance in early 2025: "Considerations for the Use of Artificial Intelligence to Support Regulatory Decision Making for Drug and Biological Products". It sets out how the FDA expects AI-generated evidence to be documented and justified in a submission. In January 2026, the FDA and EMA jointly published ten "Guiding Principles of Good AI Practice in Drug Development". These cover human oversight, risk management, data governance, and transparency across the product lifecycle — new requirements for anyone building AI into a regulatory workflow. Both documents describe AI as something that has to be governed, documented, and kept under human review, not something that replaces the regulatory judgment call. That's a materially different picture than a platform pitch that never mentions who signs off on what it produces.
The "Clinical Pharmacologist Digital Worker" Pitch — and Why This Page Used to Get It Wrong
This is where a lot of "AI regulatory intelligence" content gets ahead of itself — including an earlier version of this exact page. The pitch names a set of AI Digital Workers with job titles borrowed from a real regulatory affairs org chart. They include a Clinical Pharmacologist agent that analyzes Orange Book data and cross-references patents, a Regulatory Affairs agent, and a Competitive Intelligence agent. They're described as running on a "Mixture of Experts" system: specialized agents layered over a Neo4j knowledge graph mapping drug-target and regulatory relationships. An OpenSearch layer indexes documents underneath, with a natural-language interface for chat or voice.
We checked that roster against our own approved claims about what NextLevel has actually built. None of it is there: no Clinical Pharmacologist agent, no Regulatory Affairs agent, no Competitive Intelligence agent, no Neo4j knowledge graph, no Mixture-of-Experts architecture, no OpenSearch layer over regulatory literature. If we can't stand behind our own version of this pitch, you shouldn't take anyone else's version on faith either. That includes the version that was live on this exact page before this rewrite.
Two problems here are worth naming directly. They recur across this category rather than being unique to one vendor. First, an architecture name isn't a track record. "Mixture of Experts" and "knowledge graph" describe design patterns that plenty of real, unrelated systems use. They say nothing about whether the particular system built on top of them has ever correctly evaluated a real regulatory pathway, or flagged a real patent risk before a human caught it. Certara and Veeva lead with named customers, named regulatory-agency adoption, and named release dates. A platform that leads with its architecture diagram instead is telling you what it's built, not what it's proven. Second, querying a public database is a smaller claim than it sounds like. The FDA Orange Book, patent databases, and FDA/EMA guidance archives are genuinely public. Software that can retrieve and cross-reference them is doing real, useful work — Certara's and Veeva's tools do plenty of it. But that's a meaningfully smaller claim than software validated to make a regulatory judgment call a human would otherwise have to make. The FDA and EMA's own 2026 guiding principles draw that same distinction: AI can generate and organize information, but a qualified person still has to own the decision.
Where NextLevel.AI Actually Fits
So where does a voice AI company belong in a pharmaceutical company's regulatory affairs strategy? Not in patent monitoring, Orange Book analysis, or regulatory pathway evaluation. We don't build that, and this article isn't going to pretend otherwise. The honest answer is narrower, but still real for a lot of pharma and biotech organizations: the high-volume conversations that run around regulatory and compliance work, not inside it.
A pharmaceutical company doing serious regulatory affairs work still operates a medical information line, fielding provider and patient questions. It still logs and routes adverse-event and pharmacovigilance intake calls in real time for a human safety reviewer to assess. And it still has a regulatory affairs and compliance team that needs to be hired, onboarded, and supported like any other department. That's the same category of repetitive, high-volume, conversational work our AI Call Center and Medical AI Chatbot agents are built for: intake, triage, and routing to the licensed professional who makes the actual call. It's never a diagnosis or a regulatory judgment on the AI's part. It's also why our AI HR Assistant is a genuine fit for a regulatory affairs department's own hiring and onboarding load. That load doesn't get lighter as guidance documents and submission requirements pile up in an ever-evolving regulatory landscape. Where compliance matters — and in pharma, it always does — that work runs on infrastructure independently attested with a SOC 2 Type I report and ISO/IEC 27001:2022 certification, aligned with HIPAA, GDPR, and PDPL, across roughly 30 languages for global teams. None of that touches a patent database or a regulatory pathway decision. All of it touches the people around that work. If that narrower, honest piece is what you're evaluating, book a call and we'll tell you plainly whether it fits. That includes the parts of your regulatory operation we're not the right vendor for.
How to Evaluate Any AI Regulatory Intelligence Vendor Pitch
If you're the one being pitched a regulatory intelligence software platform, a short list of questions does more work than a features list.
Ask for a named customer or a named regulatory submission, not an architecture name. "Mixture of Experts" or "knowledge graph" describes how a system is built, not what it's done. Certara's named agency adoption is one example. So are Veeva's named customer base and dated release schedule. That's what a real, checkable track record looks like in this field.
Ask how current the underlying data and regulatory updates actually are. The Orange Book, patent-litigation status, and FDA/EMA guidance all change on their own schedule — sometimes daily. A platform that can't say how it refreshes that data is making a bigger claim than it can support. So is one that can't explain how it handles the gap between a real-world filing and its own index.
Ask whether the AI makes the regulatory call, or organizes information for the person who does. The FDA and EMA's own 2026 guiding principles draw this line deliberately. A vendor that can't draw it too is either behind the regulators' own thinking, or hoping you won't ask.
Ask what happens when it's wrong. No credible platform in this space claims zero errors. The honest pitch names a human review step and an accountability chain. A pitch that never mentions who signs off is skipping the part that matters most in a regulated industry.
Ask the question this whole piece has been trying to answer about our own earlier version of it. If you stripped out every claim that doesn't trace to a named, checkable source, how much of the pitch would still be standing?
Frequently Asked Questions
What is regulatory intelligence, and why does it matter for drug development?
Regulatory intelligence is the practice of systematically tracking regulatory pathways, health authority guidance, patent and exclusivity status, and competitive filings. It lets a pharmaceutical or biotech company make informed, actionable strategic decisions, and stay compliant as the regulatory environment evolves. That means knowing when to file, which pathway to pursue, and where a competitor might be heading in a complex regulatory landscape. Life science regulatory intelligence and strategy teams do this work because getting it wrong is expensive. A missed patent expiration or a misjudged pathway can cost months and millions — on a drug that already represents, by the most reliable published estimates, well over a billion dollars in capitalized investment.
How is artificial intelligence actually being used in regulatory affairs today?
Real, named AI-powered tools handle specific, bounded tasks. Certara's CoAuthor drafts regulatory-document content for a human writer to refine. Veeva's Vault RIM organizes registration and submission data, with agentic features for tasks like submission tracking rolling out through 2026. The FDA and EMA are themselves defining, in published guidance, how AI-generated evidence should be documented and reviewed in a submission. None of that is a single autonomous platform making regulatory decisions. It's software handling retrieval, drafting, and organization, with a qualified person still responsible for the judgment call.
Can AI actually make FDA or EMA drug approvals happen faster?
Not directly. Any pitch that implies otherwise is overreaching. FDA and EMA review timelines are set by statute and regulatory process, not by the software a sponsor uses internally. What AI-assisted regulatory intelligence software can realistically do is shorten the time a regulatory affairs team spends preparing a submission, monitoring the regulatory landscape, and drafting documents. That reduces internal delay, not the agency's own review clock.
What's the real difference between AI-assisted regulatory monitoring and a fully autonomous "AI agent" platform?
AI-assisted tools — the kind Certara and Veeva sell — support regulatory compliance work. They retrieve, organize, draft, and flag information for a regulatory affairs professional to review and act on. A pitch describing a fully autonomous platform is different. One with named "digital worker" personas making pathway or competitive-strategy judgment calls on its own is describing something no named, checkable vendor in this space currently claims to have built and validated. The FDA and EMA's own January 2026 guiding principles are explicit that human oversight stays in the loop across the product lifecycle. That's a standard a pitch should be able to meet, not just gesture at.
What should concern a life sciences company about an unproven regulatory intelligence AI pitch?
Beyond the cost of a platform that doesn't perform as described, the bigger risk is decisions made on its output: a missed patent risk, a misjudged pathway, a competitive blind spot. The FDA and EMA both now expect documented human accountability and an audit trail for AI-assisted conclusions in this function. A pitch that can't name a customer, a specific regulatory outcome, or a data-refresh process is asking a life sciences company to take that risk on faith.
How do global pharma companies manage regulatory intelligence across FDA, EMA, and other health authorities?
Global regulatory demands don't collapse into a single dashboard. In practice, companies rely on a mix of tools. Regulatory information management software is one (Veeva Vault RIM and comparable platforms). Specialized submission and pharmacometrics tools are another (Certara's suite among them). Internal regulatory affairs and competitive-intelligence staff round it out. Increasingly, agentic features are layered onto that existing software, rather than one unified platform replacing all of it. Multinational filings still route through each health authority's own process. FDA, EMA, PMDA, and others each have distinct requirements no single knowledge graph shortcuts.
What should a pharma or biotech company look for before adopting a regulatory intelligence platform?
Look for a named customer base. Look for a specific and bounded description of what the software actually automates versus assists. Look for a clear data-refresh process for sources like the Orange Book and patent filings, and an explicit human-review step that helps ensure compliance with what FDA and EMA guidance now expects. If a life sciences company's real evaluation is closer to "we need better patient- and provider-facing support around our regulatory and pharmacovigilance operations" than "we need an AI to make regulatory judgment calls," book a call with NextLevel. We'll be direct about the narrower, real piece of that we do build, and the regulatory intelligence work we don't.
About the Author
Michael Lazor is Founder and CEO of NextLevel.AI. He writes and reviews content about the economics, engineering, evaluation, and production deployment of voice AI.